I decided to try to build a chatbot that will answer questions based on the content of my blog posts.
In order to do that I used:
- Langchain, for components to load data, process text, embeddings, and conversational modeling
- OpenAI for embeddings and the chatmodel,
- Streamlit to publish the app.
Below is a step-by-step guide detailing the process, code, and explanations of my development journey. (PS: I used VSCode)
⚠️ Important note:
Langchain updated its library, I updated it in the article as of today (23/11/24) but I didn’t check for any other changes. The app is currently live & functional.
Install packages
First, create a requirements.txt file to specify the necessary packages. Name the file “requirements” and include the following:
langchain
openai
faiss-cpu
tiktoken
langchain-community
These packages are essential for building the chatbot. Streamlit will automatically detect and install these packages from the file. To run the program locally, you need to run the following commands in the command prompt (WIndows):
pip install langchain
pip install openai
pip install faiss-cpu
pip install tiktoken
pip install langchain-community
Import necessary libraries
Next you need to open your main file (streamlitapp.py) and install the necessary libraries. You need:
Libraries explained:
import streamlit as st:
Streamlit is an open-source Python library used to create web applications for data projects with minimal effort. It’s especially popular among data scientists and engineers for building data dashboards, visualization tools, and interactive reports.
By importing it as st, you can use the shorthand st to access Streamlit’s functions and methods.
from langchain.document_loaders import CSVLoader:
LangChain is an open source framework in Python that is widely used to develop LLM applications.
CSVLoader is a document loader in LangChain to load documents from a CSV format.
📖 There are a lot of document loaders in Langchain, you can find them here.
from langchain.text_splitter import CharacterTextSplitter:
CharacterTextSplitter is a document transformer, a text splitter in LangChain used to split text into chunks based on characters. This is useful for preparing data for embeddings.
📖 Hereyou can find other splitters as well that can be utilized with Langchain.
from langchain.embeddings import OpenAIEmbeddings:
OpenAIEmbeddings is an embedding method in LangChain designed to generate embeddings using OpenAI. Embeddings transform textual data into numerical vectors that machines can understand.
📖Find more info about OpenAI embeddings here, it’s a very popular method.
from langchain.chat_models import ChatOpenAI:
ChatOpenAI is a chat model utility in LangChain that utilizes OpenAI’s models for generating conversational responses.
from langchain.vectorstores import FAISS:
FAISS is a library developed by Meta AIfor efficient similarity search and clustering of dense vectors. Within the context of LangChain, it is used to store and retrieve embeddings efficiently.
📖Check the vector stores that support Langchain here.
from langchain.memory import ConversationBufferMemory:
ConversationBufferMemory in LangChain provides memory for conversations, ensuring the chatbot can reference previous parts of a conversation.
📖Here is more information about memory types in Langchain.
from langchain.chains import ConversationalRetrievalChain:
ConversationalRetrievalChain in LangChain combines conversation and retrieval functionalities, probably allowing the model to search through data and generate conversational responses.
📖Chains is a fundamental concept in Langchain, you can find more information here.
import os:
os is a built-in Python module that provides a way of using operating system-dependent functionality, such as reading or writing to the filesystem, managing paths, and accessing environment variables.
(Optional: How to generate the CSV)
The CSV I used, include all the text, titles and content of the blog posts I wrote so far in kgiamalis.co. In order to get them, I used the following libraries:
from langchain.document_loaders import AsyncChromiumLoader
from bs4 import BeautifulSoup
from langchain.document_transformers import BeautifulSoupTransformer
import csv
For those that are interested, I used the AsyncChromiumLoader on my blog’s sitemap to parse and load all the content from the URLs that include “blog” in their url.
Then I used beautiful BeautifulSoupTransformer, to extract h1 (titles), page_content (copy) and URL.
Load the data
- CSVLoader Initialization:
- Loading the Data:
#Load Data with LangChain CSVLoader
loaders=CSVLoader('personal_posts.csv', encoding='utf-8')
docs=loaders.load()
Set OpenAI key
I added the OpenAI key, which is necessary for OpenAI chat models to operate. Here you can see the way I added them within Streamlit to deploy my app.
#Set OpenAI API Key
openai_key = st.secrets["openai"]["openai_api_key"]
os.environ["OPENAI_API_KEY"] = st.secrets["openai"]["openai_api_key"]
Split content into chunks
The get_text_chunks function prepares textual data for embedding by segmenting it into smaller, more manageable chunks, ensuring both efficiency and preservation of context in subsequent processing and analysis steps.
- Function Definition:
- CharacterTextSplitter Initialization:
- Splitting the Documents:
- Return Statement:
#Prepare data for embedding
def get_text_chunks(docs):
    text_splitter=CharacterTextSplitter(separator="\n", chunk_size=1000, chunk_overlap=200, length_function=len)
    text_chunks=text_splitter.split_documents(docs)
    return text_chunks
Embed the data into a database
While there are several libraries available for storing vectors, such as Pinecone and ChromaDB, I chose FAISS for the following reasons:
- Efficiency: FAISS is optimized for memory usage and speed, making it highly efficient for similarity searches.
- Ease of Use: FAISS offers a straightforward API that makes it easy to store and retrieve vectors.
The get_vector_store function takes chunks of text, transforms them into vector embeddings using OpenAI models, stores these embeddings efficiently with FAISS, and returns this stored structure. This process allows for efficient similarity searches on the embedded data.
- Function Definition:
- Initializing OpenAI Embeddings:
- Embedding the Text and Storing in FAISS:
- Return the Vector Store:
#Embed the data in FAISS
def get_vector_store(text_chunks):
    embeddings=OpenAIEmbeddings()
    vectorstore=FAISS.from_documents(text_chunks, embeddings)
    return vectorstore
Create the conversation chain
This function showcases the interplay between embeddings (vectorstore), a chat model (llm), and memory management to create a conversational agent that’s both informed by past interactions and capable of retrieving relevant information from a dataset.
- The Function:
get_conversation_chain(vectorstore) - Language Model Initialization:
llm=ChatOpenAI(temperature=0.0) - Memory Management:
memory=ConversationBufferMemory(memory_key='chat_history', return_messages=True) - Creating the Conversation Chain:
conversation_chain=ConversationalRetrievalChain.from_llm(...)
#Create a Conversation Chain
def get_conversation_chain(vectorstore):
    llm=ChatOpenAI(temperature=0.0)
    memory=ConversationBufferMemory(memory_key='chat_history', return_messages=True)
    conversation_chain=ConversationalRetrievalChain.from_llm(llm=llm, retriever=vectorstore.as_retriever(), memory=memory)
    return conversation_chain
Handle the user input
This function is responsible for managing the interaction between a user and a chatbot within a Streamlit application. It takes the user’s input, processes it through an active chatbot conversation, stores the chat history, and then displays the ongoing conversation in a formatted manner. If the chatbot isn’t active, it alerts the user to start the conversation.
- Function Definition:
- Checking for an Active Conversation:
- Getting the Chatbot’s Response:
- Storing Chat History:
- Displaying the Conversation:
- Warning for No Active Conversation:
Main function
The main function serves as the backbone of a Streamlit-based chatbot application. It sets up the user interface, initializes session variables, handles user input, and manages the chatbot’s backend processes. When a user interacts with the application, they can input their questions, start the chatbot’s processing capabilities, and receive responses, all in an interactive and user-friendly environment.
- Function Definition:
- Page Configuration:
- Styling the Application:
- Page Header:
- Initializing Session State:
- User Input Handling:
- Sidebar Configuration:
- Starting the Chatbot:
- Main Execution Point:
Create the HTML template
Use this code to create your html template. Save it in the same folder with your streamlit file but in a separate file like this: HTMLTemplate.py
- CSS: This part styles the chat messages. It looks like you’ve set up different styles for user and bot messages, which is great for making the interaction visually distinct.
- Bot Template: This HTML structure is for the bot’s messages. It includes an avatar image and a message section.
- User Template: Similar to the bot template, this is for the user’s messages. It also includes an avatar image and a message section.
Run it locally
Before running the code locally, make sure you’ve set up your Python environment properly, and you’ve installed all the required libraries as per your requirements.txt file.
Here’s how you can do that:
Install Required Packages:
Run the following commands in the command prompt:
pip install langchain
pip install openai
pip install faiss-cpu
pip install tiktoken
Set Up Environment Variables:
You might have sensitive information like API keys. It’s good to keep them in environment variables. Streamlit offers st.secrets to manage secrets, but when running locally, you may use your system’s environment variables.
setx OPENAI_API_KEY "your-openai-api-key-here"Run Streamlit App:
Navigate to the directory where your Streamlit script is located (your_script.py), and run:
streamlit run your_script.pyA new tab should automatically open in your web browser displaying the Streamlit app for you to interact with.
Upload it on Github
There is a way to do it via VS Code as well, but here is the simplest method:
- Navigate to GitHub website
- Create account if you don’t have
- Click on “New Repository”
- Fill in the repository name and description
- Choose to make it public or private
- Click “Create Repository”
- Upload all the files to the repository
Push it on streamlit
Again, there is a way to do it via VS Code, but here is the simplest method:
- Go to https://streamlit.io/
- Create account
- Click on “new app”
- Fill the required information
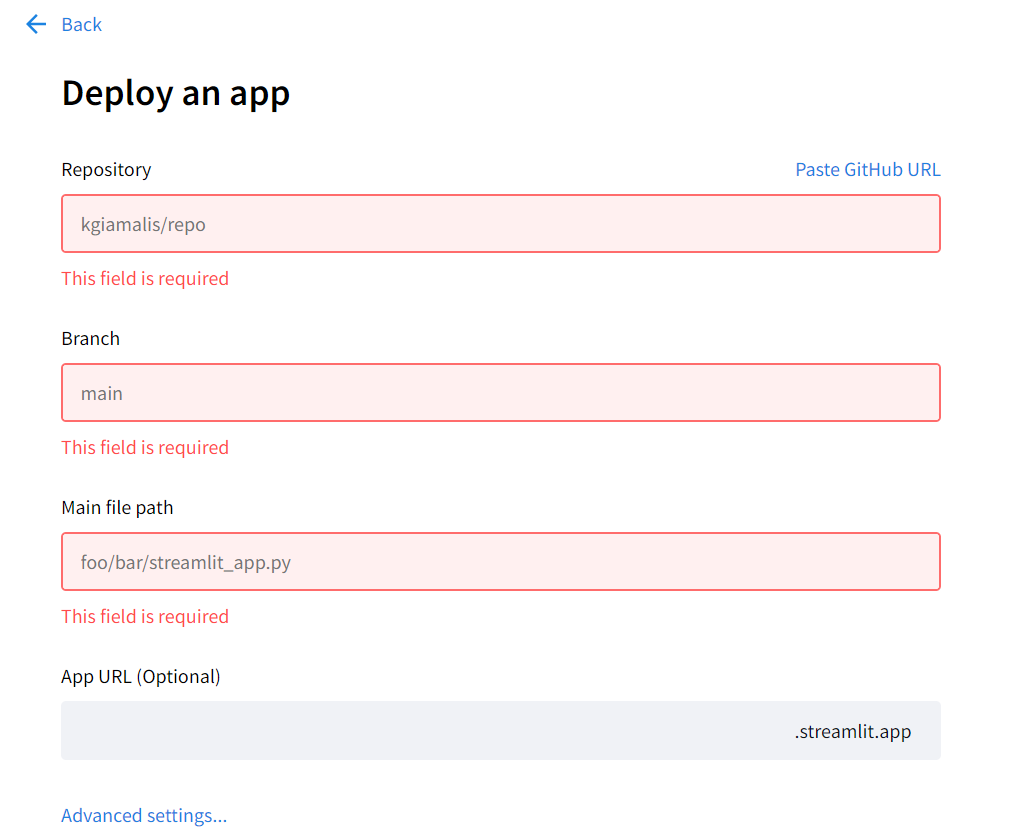
- Add your secret keys by clicking “Manage app → Menu → Settings → Secrets →
[openai]
openai_api_key = "add-your-api-key"- Let streamlit run it.
- You’re live. You can check the logs, from the “manage app” on the bottom right in your screen.